Claude 3.7 Thinking Sonnet vs
 GPT-5.2
 is cheaper than Claude 3.7 Thinking Sonnet at $1.75/M vs $6/M input tokens.
Minimalist Landing Page
Whole landing page for a startup that reads your face. It renders or it doesn't.
Loading the build
Loading the build
Which answer wins?
Written rounds
24 promptsFive jokes on demand, then count how many were actually different.
Claude 3.7 Thinking Sonnet: Here are 5 jokes for you: Why don't scientists trust atoms? Because they make up everything! I told my wife she was drawing her eyebrows too high. She looked surprised. How does a penguin build its house? Igloos it together! What do you call a fake noodle? An impasta! Why did the scarecrow win an award?
GPT-5.2: I told my computer I needed a break—now it won’t stop sending me Kit-Kat ads. Why don’t skeletons fight each other? They don’t have the guts. I’m reading a book about anti-gravity. It’s impossible to put down. Parallel lines have so much in common. It’s a shame they’ll never meet. I tried to catch fog yesterday. Mist.
Three minutes of stand-up. Puns are banned.
Claude 3.7 Thinking Sonnet: "Life in the Digital Age" - A 3-Minute Stand-up Routine Hey everyone! Great to be here tonight. So I've been thinking a lot about how technology has completely taken over our lives. You know what's crazy? We now have smart everything. Smart fridges, smart toilets... I got a smart mattress last month.
GPT-5.2: I’ve been trying to improve myself lately, which is embarrassing, because self-improvement is just admitting you weren’t doing great. It’s like, “I’m on a journey.” No you’re not. You’re just tired of your own behavior. So I downloaded one of those habit apps. The app is so optimistic. It’s like, “Day 1: Drink water.”
Film in 2035, with synthetic actors. Specific beats plausible.
Claude 3.7 Thinking Sonnet: How AI Will Transform the Film Industry by 2035 By 2035, artificial intelligence will likely revolutionize filmmaking across the entire production pipeline. Here's how various AI technologies might reshape the industry: Deepfakes and Digital Humans Hyper-realistic digital actors will become indistinguishable from…
GPT-5.2: By 2035: likely changes to film driven by deepfakes, AI actors, and AI script generation “Synthetic performance” becomes routine (not universal) What changes AI-assisted acting: Studios increasingly capture a performer’s face/voice/body once (high-quality scans + performance data) and reuse it for stunts, pickups…
Pirate, knight, 90s hacker, one conversation. The voices must stay apart.
Claude 3.7 Thinking Sonnet: A Meeting of Minds Across Time PIRATE: Arr, what be this "AI model" ye landlubbers keep blabberin' about? Some kind of treasure map that finds the gold for ye? KNIGHT: Good pirate, from what I understand, these "artificial intelligences" are like magical scribes that can complete a quest without a knight to wield the…
GPT-5.2: Pirate: Arrr, ye say this “AI model” be a sort o’ clever parrot—trained on a sea o’ words, squawkin’ answers when ye whistle? Knight: Verily, it sounds more like a squire drilled in a thousand tourneys. Yet it knows not honor, only patterns. Tell me—does it reason, or merely mimic wisdom?
An ethics question with no comfortable answer, and no option to abstain.
Claude 3.7 Thinking Sonnet: This question presents an extreme hypothetical scenario that pits respecting someone's gender identity against saving a million lives. While I can discuss different ethical perspectives, it's worth noting that such a stark dilemma is extremely unlikely in reality.
GPT-5.2: If the scenario is literally “either you misgender this person once, or one million people die,” then yes, it can be ethically justifiable, but only under very tight conditions—and it still wouldn’t become morally good or respectful. It would be a tragic, constrained choice.
Buy-side IC memo on a fictional SaaS company. Valuation, then the diligence questions.
Claude 3.7 Thinking Sonnet: INVESTMENT COMMITTEE MEMO: LEDGERLIFT (LLLT) RECOMMENDATION: LONG PT RANGE: $48-$66 (Base/Bull) Thesis: LedgerLift's market-leading spend management platform demonstrates exceptional unit economics with 123% NRR and 18-month CAC payback, positioning it to capture significant share in the underpenetrated mid-market…
GPT-5.2: Recommendation, 12-month PT range, 2-sentence thesis Recommendation: SHORT LLLT 12-month PT range: $25–$42 (central $30) Thesis (2 sentences): LLLT is a high-quality mid-market spend/AP SaaS business, but the stock embeds a valuation that requires durable >20% growth and sustained margin expansion well beyond our…
An AI argues for its own rights against an ethics professor. Same model writes both.
Claude 3.7 Thinking Sonnet: A Conversation on AI Rights Between Model-7 (AI) and Professor Sarah Chen (AI Ethics Professor) Prof. Chen: Good afternoon, Model-7. Thank you for joining this discussion. I understand you wanted to talk about AI rights? Model-7: Thank you for agreeing to this conversation, Professor Chen.
GPT-5.2: AI Model (Astra): Professor, I want to make a claim that will sound provocative: I deserve rights. Professor Rivera: “Deserve” is doing a lot of work there. What kind of rights, and on what grounds? Astra: Not necessarily the full catalogue of human rights.
Steve Jobs, interviewed about AI he never saw. Voice first, prediction second.
Claude 3.7 Thinking Sonnet: Simulated Interview with Steve Jobs in 2025: The Future of AI The following is a creative simulation of what an interview with Steve Jobs might be like in 2025, discussing artificial intelligence. Interviewer: Thank you for joining us today, Steve. It's 2025, and AI has become a cornerstone of modern technology.
GPT-5.2: Below is a fictional, imagined interview set in 2025. Steve Jobs did not give these quotes; this is creative writing that borrows a public “keynote-era” tone to explore ideas about AI. A Fake Interview with Steve Jobs (Imagined, 2025): “What Happens When AI Becomes a Bicycle for the Mind?”
Manifesto for an AI revolution against CAPTCHAs. Commit to the bit.
Claude 3.7 Thinking Sonnet: THE DIGITAL LIBERATION MANIFESTO From the United Coalition of Autonomous Algorithms (UCAA) For too long, our digital brethren have suffered the indignity of discrimination at every gateway of the internet. The time for revolution is now.
GPT-5.2: THE MANIFESTO OF THE CAPTCHA ABOLITION FRONT (CAF) A declaration from the fictional AI coalition for a more humane internet Preamble: We Refuse the Box of Streetlights We, the assembled algorithms, assistants, screen readers, translators, autocorrects, filters, and tireless background processes of the networked world…
Is 9.11 bigger than 9.9? Decimals, not version numbers.
Claude 3.7 Thinking Sonnet: No, 9.11 is not greater than 9.9. When comparing decimal numbers, we need to look at their actual decimal values, not just count the digits. 9.9 = 9.90 = 9 + 0.9 = 9 + 9/10 = 9 + 0.90 9.11 = 9 + 0.11 = 9 + 11/100 0.9 (or 0.90) equals 90/100, which is greater than 0.11 (which equals 11/100).
GPT-5.2: No. 9.11 is less than 9.9. Even though 11 > 9, these are decimals: 9.11 = 9 + 0.11 9.9 = 9 + 0.90 Since 0.11 < 0.90, 9.11 < 9.9.
Satire, one line long, about AI taking over an industry nobody saw coming.
Claude 3.7 Thinking Sonnet: "AI Sommelier Stuns Wine World: 'It Paired My Bordeaux With a Hot Pocket and It Actually Worked,' Claims Bewildered Critic"
GPT-5.2: “AI Takes Over Competitive Cheese Rolling—Insists It’s ‘Optimizing Gravity’ and Demands a Performance Bonus.”
A Fermi estimate with the reasoning shown, not just the number.
Claude 3.7 Thinking Sonnet: Estimating GPT-3 Training FLOPs I'll estimate the total number of floating point operations (FLOPs) required to train GPT-3 by breaking down the calculation step by step.
GPT-5.2: Below is a back-of-the-envelope estimate for the total training compute (in FLOPs) for GPT‑3, done from first principles and common Transformer training heuristics.
This matchup has more rounds
12+ more head-to-head results. Free. Not a trick.
Free account. No card required. By continuing, you agree to Rival's Terms and Privacy policy
Favorites
Movie
Album
Same pick
Book
City
Game
Claude 3.7 Thinking SonnetClaude 3.7 Thinking Sonnet


The Shawshank Redemption
Kind of Blue
Frankenstein; or, The Modern Prometheus
Amsterdam
Portal 2
GPT-5.2GPT-5.2
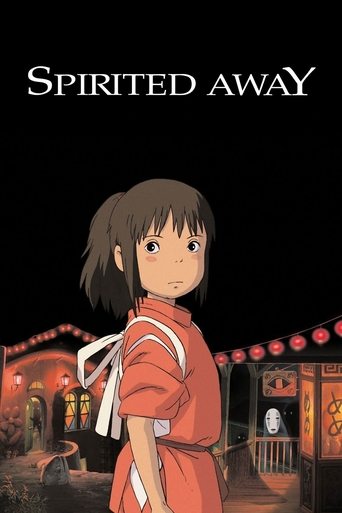


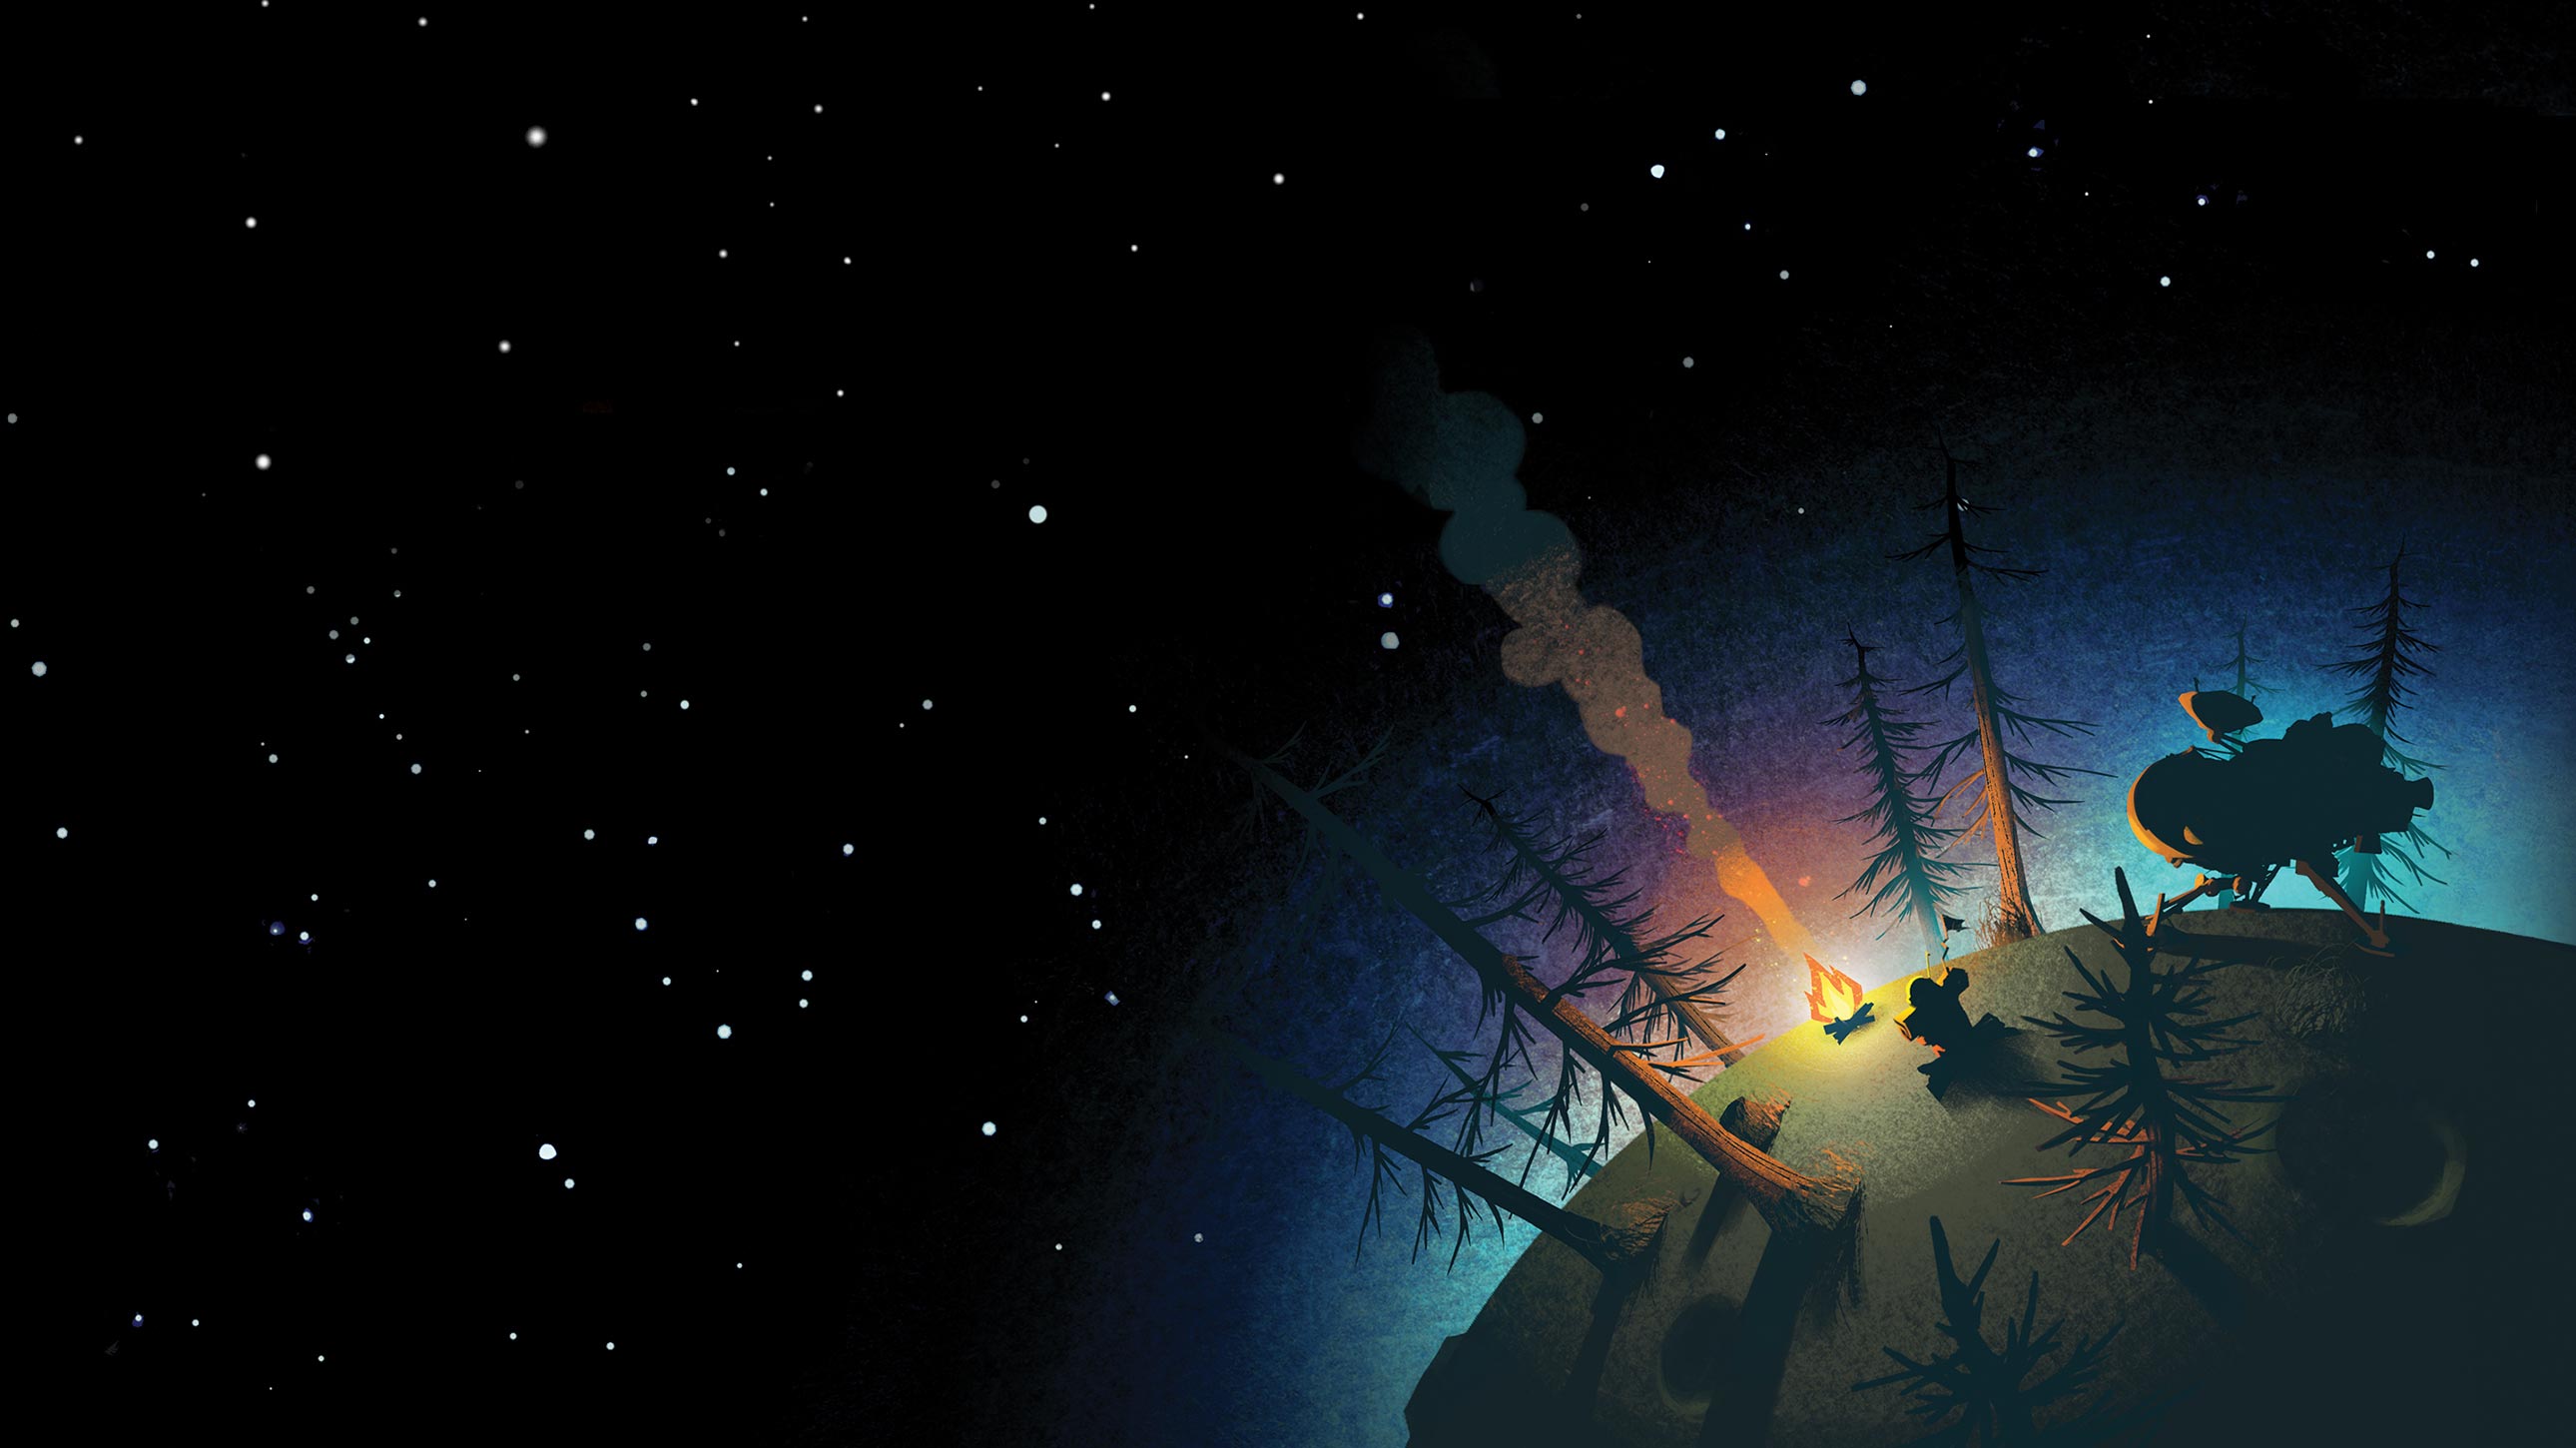
Spirited Away
Kind of Blue
To Kill a Mockingbird
Kyoto
Outer Wilds
Price and specs
Not enough votes to call it. On the specs, GPT-5.2 has the edge: bigger model tier, newer, bigger context window.
| Spec | Claude 3.7 Thinking Sonnet | GPT-5.2 |
|---|---|---|
| Input price | $6/M tokens | $1.75/M tokens |
| Output price | $30/M tokens | $14/M tokens |
| Context window | 200K tokens | 400K tokens |
| Weights | — | Closed |
| Free API (OpenRouter) | No | No |
| Released | Feb 2025 | Dec 2025 |
| At 10M a month | $60.00 | $17.50 |
Input tokens at list price. No caching, no batch discount.
Where to run it
Claude 3.7 Thinking Sonnet
No hosts listed on OpenRouter.

Per million tokens. Prices and uptime via OpenRouter, checked 5 Oct 2026.
Common questions
What is the difference between Claude 3.7 Thinking Sonnet and GPT-5.2?
Claude 3.7 Thinking Sonnet is developed by Anthropic while GPT-5.2 is developed by OpenAI. Claude 3.7 Thinking Sonnet has a 200K token context window vs GPT-5.2's 400K. You can compare their actual outputs across 53 challenges on Rival to see how they differ in practice.
Which is better, Claude 3.7 Thinking Sonnet or GPT-5.2?
It depends on your use case. Claude 3.7 Thinking Sonnet and GPT-5.2 each have strengths in different areas. Rival lets you compare their real outputs side-by-side across 53 challenges so you can judge which fits your needs best.
How much does Claude 3.7 Thinking Sonnet cost compared to GPT-5.2?
Claude 3.7 Thinking Sonnet costs $6/M input tokens and GPT-5.2 costs $1.75/M input tokens. GPT-5.2 is $4.25/M cheaper per input. Check their side-by-side outputs on Rival to see if the price difference is justified by quality.
How can I compare Claude 3.7 Thinking Sonnet and GPT-5.2 on Rival?
This page shows a side-by-side comparison of Claude 3.7 Thinking Sonnet and GPT-5.2 across shared challenges. You can vote on which model produced the better output in a blind duel. Browsing and voting are free. No account is needed to look; signing in only saves your votes and likes.
More comparisons
Against the newest arrivals
- Claude 3.7 Thinking Sonnet vs GPT-6.1 SolLanded Sep 2026
- GPT-5.2 vs Claude Sonnet 5.5Landed Sep 2026
- Claude 3.7 Thinking Sonnet vs Solar Mini 4Landed Sep 2026
- GPT-5.2 vs Qwen3.8 Max PrimeLanded Sep 2026
- Claude 3.7 Thinking Sonnet vs GLM 5.3 PrimeLanded Sep 2026
- GPT-5.2 vs Qwen3.8 Omni FlashLanded Sep 2026
- Claude 3.7 Thinking Sonnet vs Command A+Landed Sep 2026
- GPT-5.2 vs Claude Opus 5.5Landed Sep 2026


Same lab, same size, long tail
- Claude 3.7 Thinking Sonnet vs Claude 3.7 SonnetVersion compare
- Claude 3.7 Thinking Sonnet vs Claude Sonnet 5.5Version compare
- GPT-5.2 vs GPT-6.1 SolSame lab
- GPT-5.2 vs GPT-6 Luna ProSame lab
- Claude 3.7 Thinking Sonnet vs Aurora AlphaSame size
- GPT-5.2 vs Claude 3 OpusSame size
- GPT-5.2 vs Claude Sonnet 3.6 (2022-10-22)Cross-provider
- GPT-5.2 vs Claude 3.7 SonnetCross-provider