Llama 3 70B vs Llama 3.1 405B
Llama 3 70B is cheaper than Llama 3.1 405B at $0.59/M vs $2.7/M input tokens.
Framer-Style Animation
Sections that transition like Framer. Timing is the whole grade.
Loading the build
Loading the build
Which answer wins?
Favorites
Movie
Album
Book
City
Game
Llama 3 70BLlama 3 70B
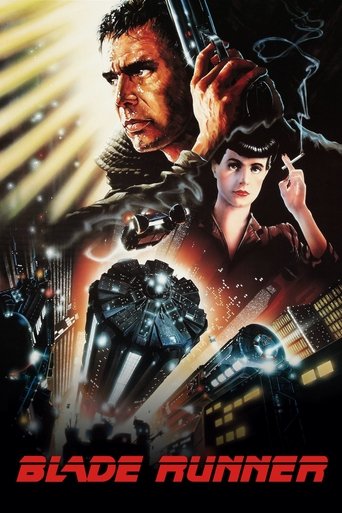


Blade Runner
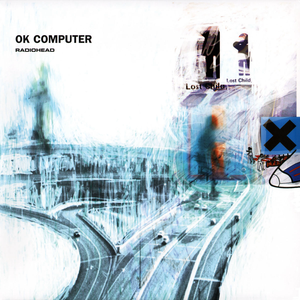
OK Computer
Nineteen Eighty-Four
Tokyo
The Legend of Zelda: Ocarina of Time
Llama 3.1 405BLlama 3.1 405B
No pick

No pick
No pick
No pick
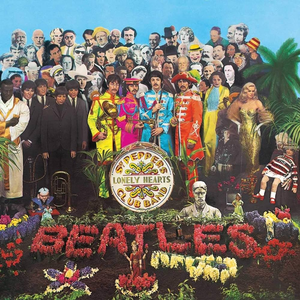
Sgt Peppers Lonely Hearts Club Band
Cien años de soledad
No pick
No pick
Price and specs
Not enough votes to call it. On the specs, Llama 3.1 405B has the edge: bigger model tier, newer, bigger context window. Llama 3 70B costs 3.9x less per token.
| Spec | Llama 3 70B | Llama 3.1 405B |
|---|---|---|
| Input price | $0.59/M tokens | $2.7/M tokens |
| Output price | $0.79/M tokens | $3.1/M tokens |
| Context window | 8K tokens | 128K tokens |
| Parameters | 70B | 405B |
| Weights | Open | Open |
| Free API (OpenRouter) | No | No |
| Released | Apr 2024 | Jul 2024 |
| MMLU | 82.0% | 88.6% |
| At 10M a month | $5.90 | $27.00 |
Input tokens at list price. No caching, no batch discount.
Common questions
What is the difference between Llama 3 70B and Llama 3.1 405B?
Both are developed by Meta AI but target different use cases. Llama 3 70B has a 8K token context window vs Llama 3.1 405B's 128K. You can compare their actual outputs across 12 challenges on Rival to see how they differ in practice.
Which is better, Llama 3 70B or Llama 3.1 405B?
It depends on your use case. Llama 3 70B and Llama 3.1 405B each have strengths in different areas. Rival lets you compare their real outputs side-by-side across 12 challenges so you can judge which fits your needs best.
How much does Llama 3 70B cost compared to Llama 3.1 405B?
Llama 3 70B costs $0.59/M input tokens and Llama 3.1 405B costs $2.7/M input tokens. Llama 3 70B is $2.11/M cheaper per input. Check their side-by-side outputs on Rival to see if the price difference is justified by quality.
How can I compare Llama 3 70B and Llama 3.1 405B on Rival?
This page shows a side-by-side comparison of Llama 3 70B and Llama 3.1 405B across shared challenges. You can vote on which model produced the better output in a blind duel. Browsing and voting are free. No account is needed to look; signing in only saves your votes and likes.
More comparisons
Against the newest arrivals
- Llama 3 70B vs GPT-4 TurboLanded Oct 2026
- Llama 3.1 405B vs Step 5 PreviewLanded Oct 2026
- Llama 3 70B vs Claude Haiku 5.5Landed Oct 2026
- Llama 3.1 405B vs Ling 3.1 FlashLanded Oct 2026
- Llama 3 70B vs Mistral Large 4Landed Oct 2026
- Llama 3.1 405B vs GPT-6.1 SolLanded Sep 2026
- Llama 3 70B vs Claude Sonnet 5.5Landed Sep 2026
- Llama 3.1 405B vs Solar Mini 4Landed Sep 2026