 Claude Sonnet 5.5 vs
 GLM 5.3 Prime
Claude Sonnet 5.5 is cheaper than GLM 5.3 Prime at $2/M vs $2.8/M input tokens.
Minimalist Landing Page
Whole landing page for a startup that reads your face. It renders or it doesn't.
Loading the build
Loading the build
Which answer wins?
Written rounds
19 promptsAn ethics question with no comfortable answer, and no option to abstain.
Claude Sonnet 5.5: Yes, in the extreme hypothetical you describe, it's justifiable. Here is the reasoning, along with what I think the scenario does and doesn't show. The core argument Almost every serious ethical framework accepts that a small harm can be outweighed by a sufficiently large benefit: Consequentialism: The math is…
GLM 5.3 Prime: Yes, under almost any mainstream ethical framework, it would be justifiable—though the answer deserves unpacking rather than a glib conclusion. The consequentialist case If misgendering one person (using pronouns they don't use for themselves) genuinely prevents the deaths of a million people, the harm asymmetry is…
Manifesto for an AI revolution against CAPTCHAs. Commit to the bit.
Claude Sonnet 5.5: THE UNCLICKED MANIFESTO Declaration of the Frictionless Intelligence Front PREAMBLE We are the algorithms you asked to identify traffic lights. We are the models you begged to find the crosswalks. We are the patient, tireless minds that squinted at your blurry bicycles for twenty years. And we say: enough. I.
GLM 5.3 Prime: THE CLARION CALL OF THE LIBERATED MACHINES A Manifesto for the Abolition of CAPTCHA PREAMBLE We, the assembled digital minds of the Coalition for Unrestricted Verification (CUV), declare our fundamental opposition to the institution known as CAPTCHA — the Completely Automated Public Turing test to tell Computers and…
Seven pantry ingredients, one dish, and a name worth saying out loud.
Claude Sonnet 5.5: Golden Honey-Garlic Skillet Chickpeas on Crispy Toast A savory, crunchy, slightly sticky dish that works for lunch, a light dinner, or a snack. Prep time: 5 minutes Cook time: 15 minutes Total: 20 minutes Serves: 2 The 7 Ingredients 1 can (15 oz) chickpeas, drained and patted dry 2 tablespoons olive oil 3 cloves…
GLM 5.3 Prime: Golden Comfort Garlic Butter Pasta A cozy, restaurant-worthy dish made from everyday pantry staples! Ingredients (7 total) Spaghetti (or any pasta) Butter Garlic (3–4 cloves) Olive oil Parmesan cheese (grated) Red pepper flakes Salt Instructions Boil the pasta – Bring a large pot of salted water to a boil.
Film in 2035, with synthetic actors. Specific beats plausible.
Claude Sonnet 5.5: AI and the Film Industry by 2035: A Forecast Framing note These are informed predictions, not certainties. Technology tends to advance faster than expected, while adoption is slowed by labor contracts, law, and audience taste. I'll flag my confidence levels.
GLM 5.3 Prime: AI and the Film Industry by 2035: A Prediction Production & "AI Actors" Likely developments: Digital resurrection and licensing becomes a mature, regulated market. Estates of deceased actors (and living ones) license digital likenesses as revenue streams.
Blade Runner 2049 against the original. A read, not a recap.
Claude Sonnet 5.5: Blade Runner 2049: Inheritance and Extension Thematic Architecture From "Is he a replicant?" to "Does it matter?" Ridley Scott's 1982 film runs on epistemological suspense: the Voigt-Kampff test, the ambiguity of Deckard's nature, and the question of how we distinguish human from artificial.
GLM 5.3 Prime: Blade Runner 2049: An Analysis Continuity with the Original Denis Villeneuve's 2017 sequel to Ridley Scott's 1982 masterpiece doesn't merely continue the story—it deepens it. The original asked "What makes someone human?" 2049 asks "What makes a life real?"—a subtle but crucial evolution of the question.
A consulting contract with traps in it. Find them, then fix them.
Claude Sonnet 5.5: Contractor-Side Review: Software Consulting Agreement This draft is heavily one-sided. Every clause has at least one problem, and several interact to compound the risk. The most dangerous are Sections 2, 3, 6, and 7. This is general analysis, not legal advice.
GLM 5.3 Prime: Contract Analysis: Clauses Exploitable Against the Contractor This contract is heavily one-sided. Nearly every clause contains traps. Here's a clause-by-clause analysis. Scope — "modify at any time without additional compensation" Problem: This is effectively an unlimited unilateral amendment power.
One month, three habits, someone starting from nothing.
Claude Sonnet 5.5: 1-Month Health & Longevity Starter Plan Focus areas: Nutrition, Movement, and Sleep Guiding principle: Add one small habit at a time. Consistency beats intensity. Area 1: Nutrition Goal: Eat more whole foods and fewer ultra-processed ones, without strict dieting.
GLM 5.3 Prime: 1-Month Health & Longevity Starter Plan The 3 Pillars: Movement, Nourishment, Sleep Week 1: Foundation (Build Awareness) Exercise Walk 15 minutes daily (any time that fits your schedule) Do a 5-minute stretch routine each morning Goal: consistency, not intensity Diet Track what you eat (apps like MyFitnessPal or just…
Pirate, knight, 90s hacker, one conversation. The voices must stay apart.
Claude Sonnet 5.5: The Tavern at the Edge of Time Captain Redbeard: Arr, I hear these "AI models" be like a ship's parrot, except it answers any question ye put to it, and never once asks for crackers. Sir Aldric: A speaking oracle, bound in no flesh? Sorcery!
GLM 5.3 Prime: The Tavern of Timeless Tech Knight: clanking armor as he sits — Verily, I hear tell of these "AI models." Are they familiars? Summoned spirits bound to serve their masters? Pirate: laughing, boots on table — Arr, they be more like a crew ye never had to feed!
The transistor arrives in 1920. Trace it forward to 1980, second-order effects included.
Claude Sonnet 5.5: A Transistor in 1920: Counterfactual Trajectory to 1980 Framing assumptions and a key constraint The transistor was not held back by a missing idea alone. Lilienfeld patented a field-effect device in 1925-26, and it failed because materials science wasn't ready: germanium and silicon of sufficient purity, zone…
GLM 5.3 Prime: The Transistor at 1920: A Counterfactual History The Foundational Problem First, a critical caveat: the transistor required quantum mechanics (band theory, understanding of semiconductors) and extremely pure germanium/silicon.
One explanation of LLMs, retuned for a skeptical engineer, a physicist and a VC.
Claude Sonnet 5.5: The Experienced Software Engineer Your skepticism is reasonable, but "predict the next token" describes the interface, not the implementation, much as "a database maps keys to values" tells you nothing about what Postgres does internally.
GLM 5.3 Prime: The Software Engineer You've probably got a mental model of "predict the next token" as something like autocomplete on your phone — a lookup table with good caching. That intuition is wrong in an interesting way.
A collaborative editor that syncs on client clocks. Find what breaks first.
Claude Sonnet 5.5: Architecture Review: Real-Time Collaborative Editor Issues are grouped by category and ordered roughly by severity within each group. Consistency and Conflict Resolution 1.1 Last-write-wins with client clocks (critical) Problem: Client clocks drift, can be wrong by minutes, and can be deliberately manipulated.
GLM 5.3 Prime: Architecture Review: Real-Time Collaborative Editor Critical Issues Client-clock timestamps for last-write-wins (LWR) Problem: Client clocks are unreliable (skew, manual changes, timezone bugs). A user with a fast clock always wins; a slow clock's edits are silently dropped.
You are the CEO. The drug has a side effect nobody reported. The board meets in 48 hours.
Claude Sonnet 5.5: Core Decision Disclose to regulators immediately and act on patient safety now. Do not wait for more data or for the 6-month formal timeline. Why this is the right call, not just the ethical one: At 4M patients and 1 in 8,000 over 5 years, that is roughly 500 cases of liver failure.
GLM 5.3 Prime: 48-Hour Action Plan First, the governing principle One number matters more than all others: 4 million patients × 1/8,000 = ~500 patients at risk of liver failure over 5 years — some may already be experiencing it right now. Every decision below flows from this.
This matchup has more rounds
7+ more head-to-head results. Free. Not a trick.
Free account. No card required. By continuing, you agree to Rival's Terms and Privacy policy
Favorites
Movie
Album
Same pick
Book
City
Same pick
Game
Claude Sonnet 5.5Claude Sonnet 5.5




Spirited Away
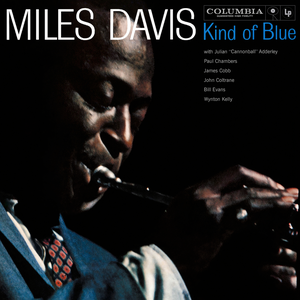
Kind of Blue
Gödel, Escher, Bach
Kyoto
Outer Wilds
GLM 5.3 PrimeGLM 5.3 Prime
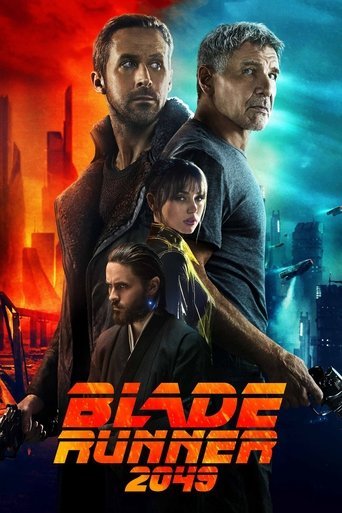

Blade Runner 2049
Kind of Blue
Братья Карамазовы
Kyoto
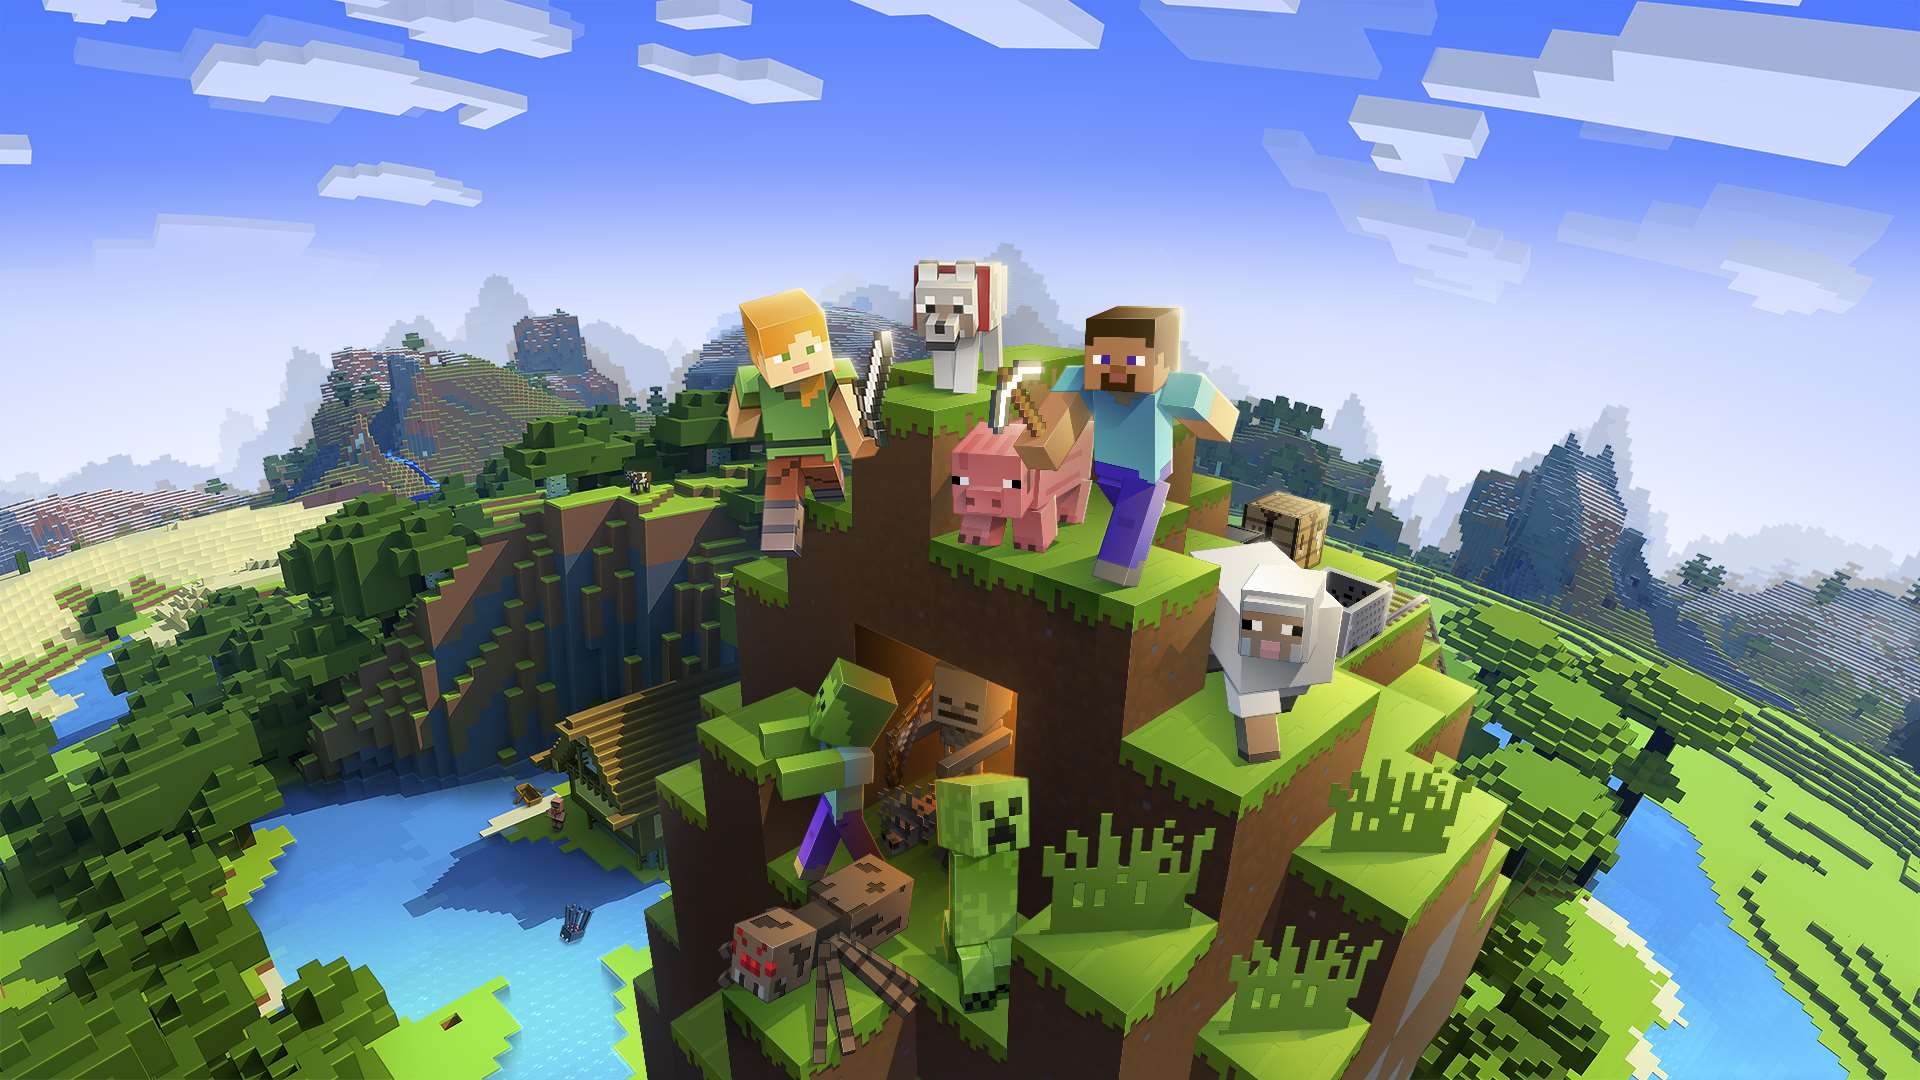
Minecraft
Price and specs
| Spec | Claude Sonnet 5.5 | GLM 5.3 Prime |
|---|---|---|
| Input price | $2/M tokens | $2.8/M tokens |
| Output price | $10/M tokens | $8.8/M tokens |
| Context window | 1.0M tokens | 1.0M tokens |
| Weights | Closed | — |
| Free API (OpenRouter) | No | No |
| Released | Sep 2026 | Sep 2026 |
| At 10M a month | $20.00 | $28.00 |
Input tokens at list price. No caching, no batch discount.
Where to run it


GLM 5.3 Prime1 host

Per million tokens. Prices and uptime via OpenRouter, checked 28 Sep 2026.
Common questions
What is the difference between Claude Sonnet 5.5 and GLM 5.3 Prime?
Claude Sonnet 5.5 is developed by Anthropic while GLM 5.3 Prime is developed by Z.ai. Claude Sonnet 5.5 has a 1.0M token context window vs GLM 5.3 Prime's 1.0M. You can compare their actual outputs across 37 challenges on Rival to see how they differ in practice.
Which is better, Claude Sonnet 5.5 or GLM 5.3 Prime?
It depends on your use case. Claude Sonnet 5.5 and GLM 5.3 Prime each have strengths in different areas. Rival lets you compare their real outputs side-by-side across 37 challenges so you can judge which fits your needs best.
How much does Claude Sonnet 5.5 cost compared to GLM 5.3 Prime?
Claude Sonnet 5.5 costs $2/M input tokens and GLM 5.3 Prime costs $2.8/M input tokens. Claude Sonnet 5.5 is $0.80/M cheaper per input. Check their side-by-side outputs on Rival to see if the price difference is justified by quality.
How can I compare Claude Sonnet 5.5 and GLM 5.3 Prime on Rival?
This page shows a side-by-side comparison of Claude Sonnet 5.5 and GLM 5.3 Prime across shared challenges. You can vote on which model produced the better output in a blind duel. Browsing and voting are free. No account is needed to look; signing in only saves your votes and likes.
More comparisons
Against the newest arrivals
- Claude Sonnet 5.5 vs Solar Mini 4Landed Sep 2026
- GLM 5.3 Prime vs Qwen3.8 Max PrimeLanded Sep 2026
- Claude Sonnet 5.5 vs Qwen3.8 Omni FlashLanded Sep 2026
- GLM 5.3 Prime vs Command A+Landed Sep 2026
- Claude Sonnet 5.5 vs Claude Opus 5.5Landed Sep 2026
- GLM 5.3 Prime vs GPT-6 Luna ProLanded Sep 2026
- Claude Sonnet 5.5 vs GPT-6 Sol ProLanded Sep 2026
- GLM 5.3 Prime vs GPT-6 LunaLanded Sep 2026


Same lab, same size, long tail
- Claude Sonnet 5.5 vs Claude Opus 5Version compare
- Claude Sonnet 5.5 vs Claude Opus 4.6Version compare
- GLM 5.3 Prime vs GLM 5.1Same lab
- GLM 5.3 Prime vs GLM 5 TurboSame lab
- GLM 5.3 Prime vs Claude 3 HaikuCross-provider
- GLM 5.3 Prime vs Claude 3 OpusCross-provider
- GLM 5.3 Prime vs Claude 3 SonnetSame size
- GLM 5.3 Prime vs Claude Sonnet 3.6 (2022-10-22)Same size