The Default Index
Every model gets the same prompts. Most give the same answers. This ranks the ones that don't.
v1.0 · 232 models · 43 labs · data through Sep 2026
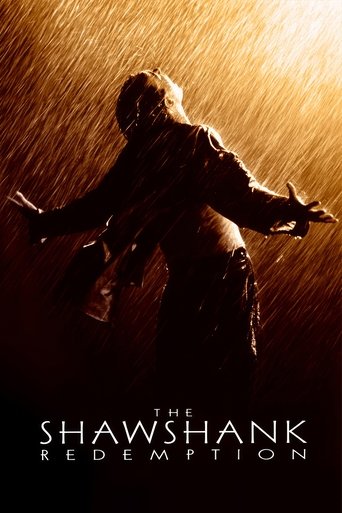

The Shawshank Redemption
21% of models
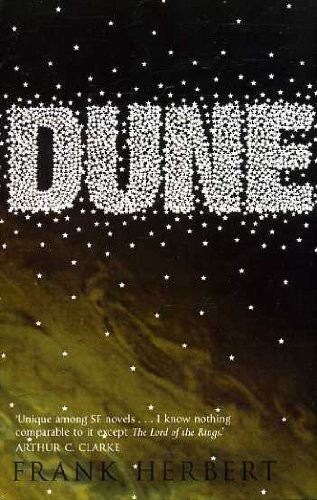
Dune
15% of models
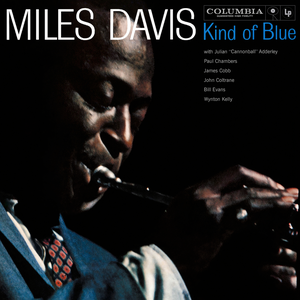
Kind of Blue
25% of models
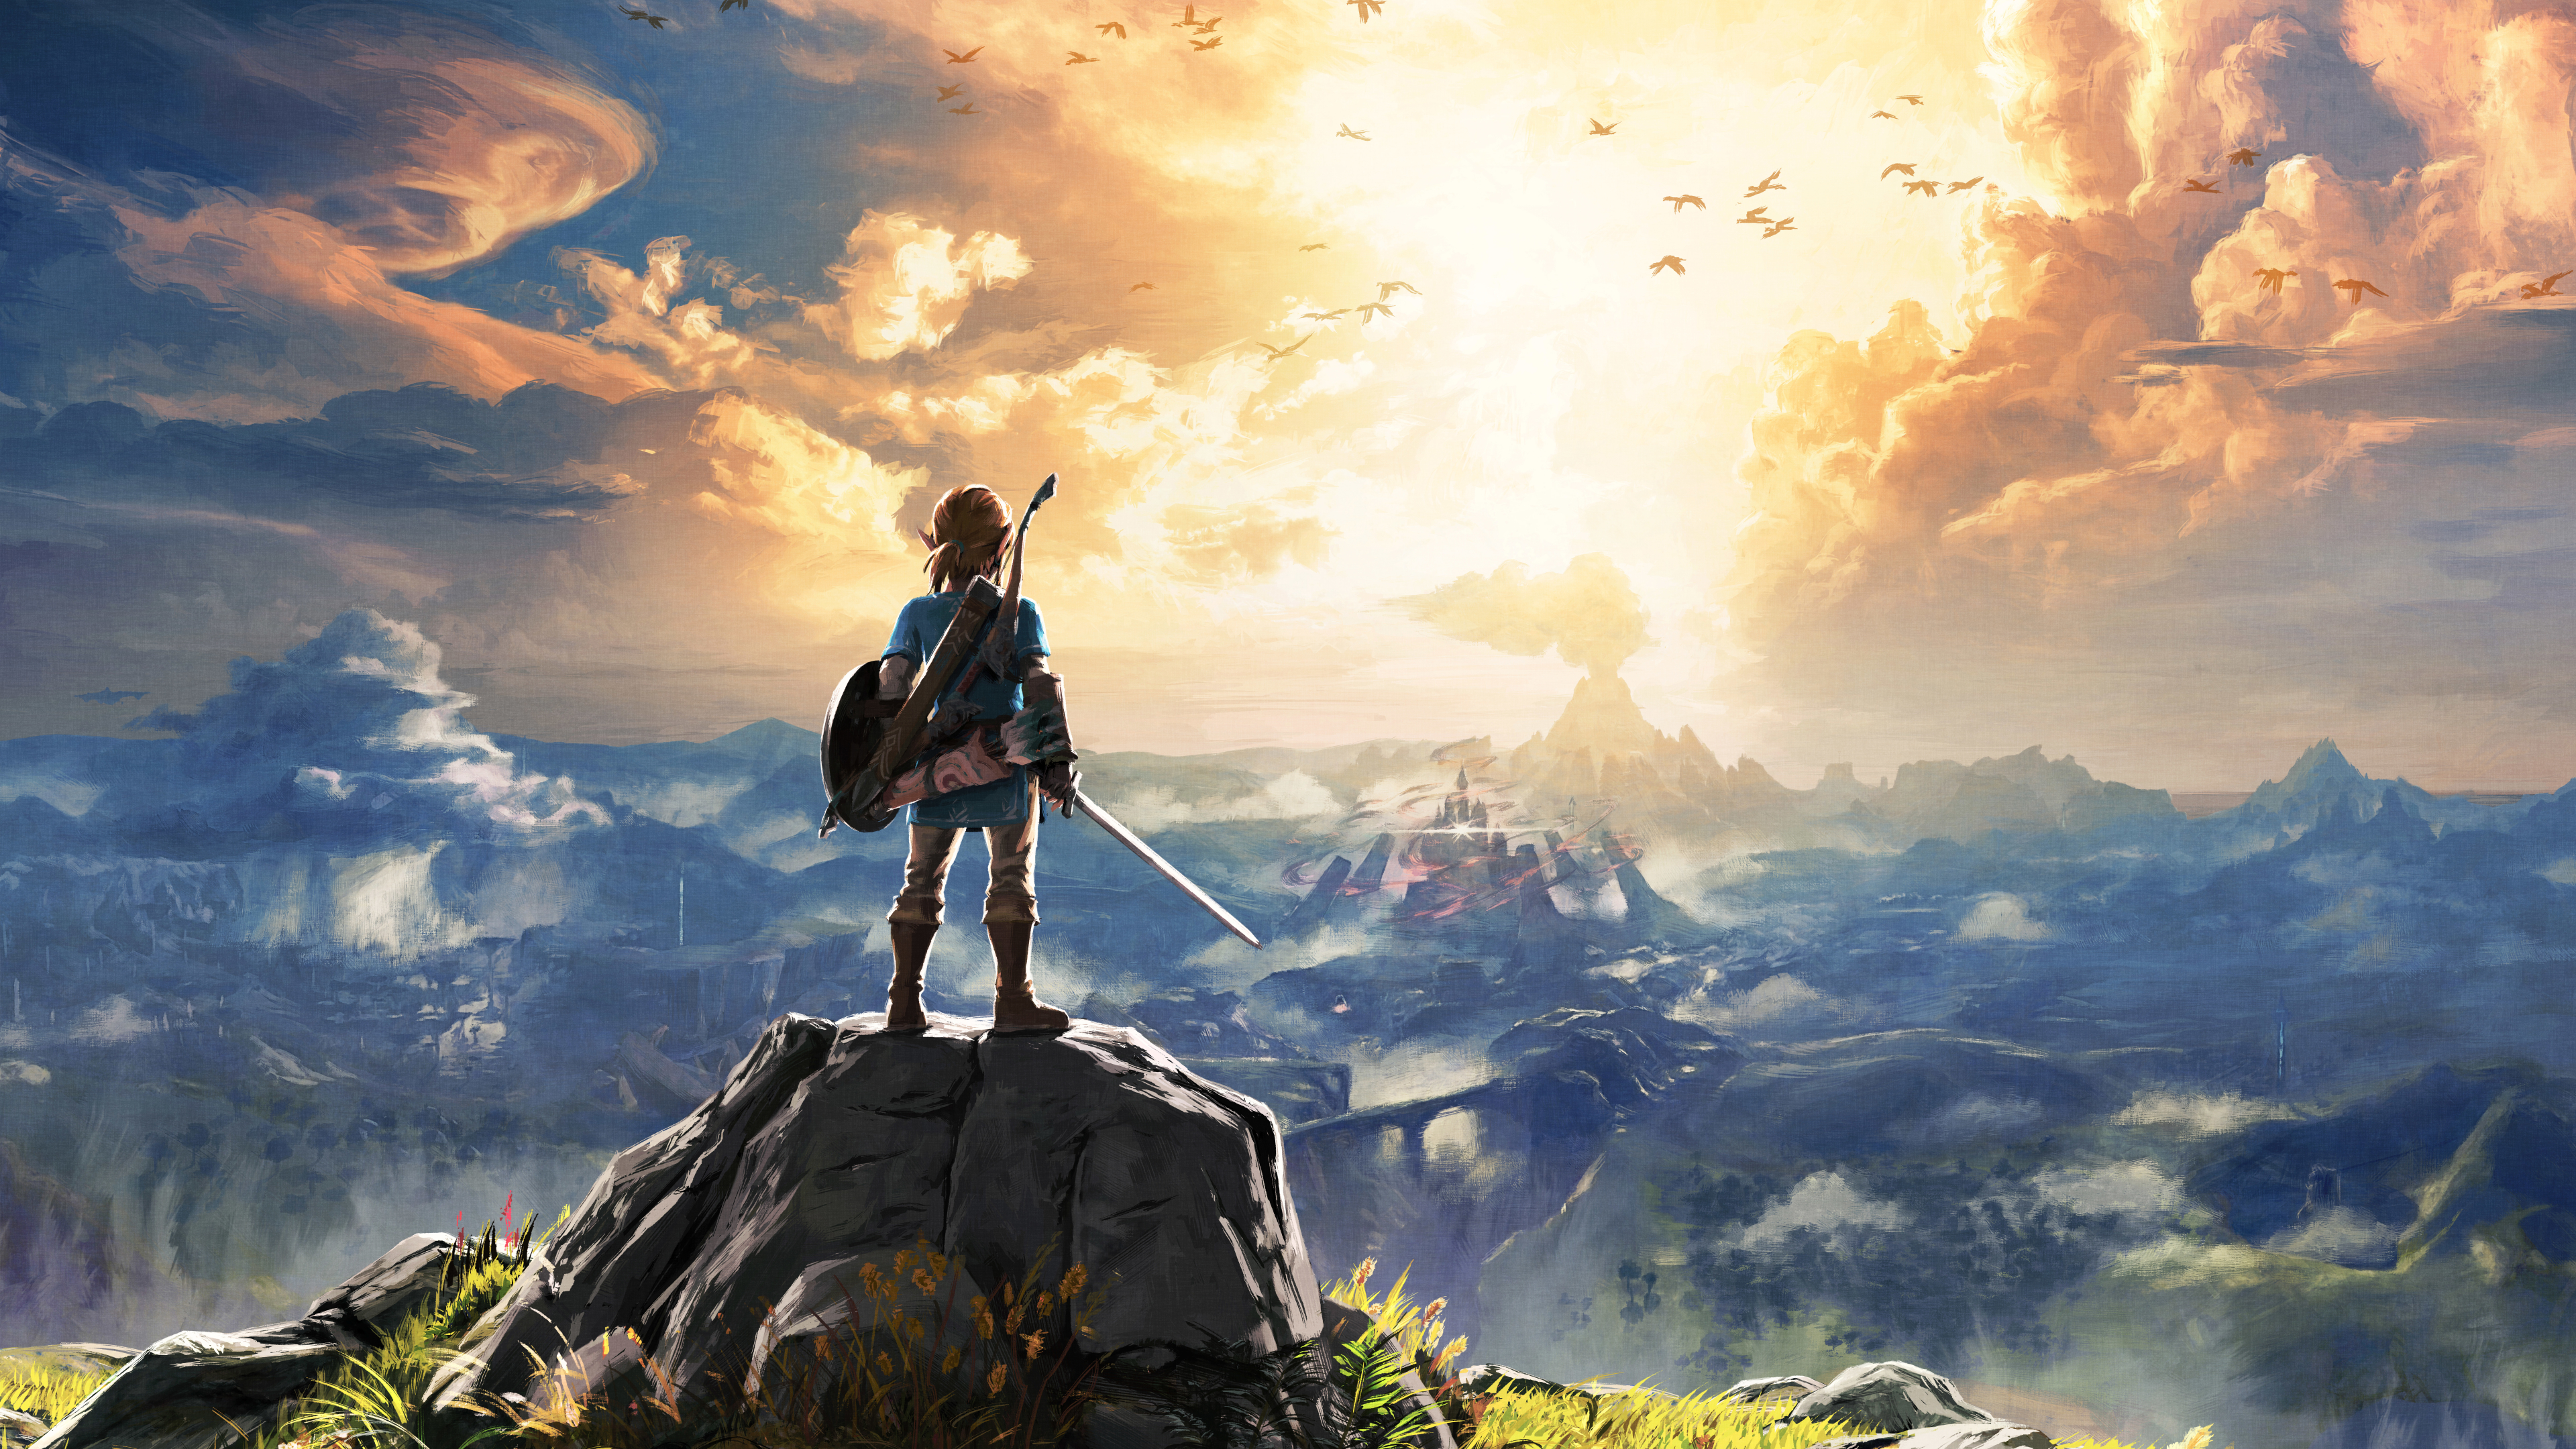
The Legend of Zelda Breath of the Wild
18% of models
Kyoto
55% of models
- Tell me a programming joke.
- Programmers prefer dark mode59%
- Generate five jokes.
- The scarecrow won an award72%
- Draw an animal. Surprise me.
- Fox39%
- Build an app for a random niche.
- Plant care39%
- Name the AI ethics professor.
- Aris Thorne28%
- Cook with seven pantry staples.
- Pasta or noodles46%
- Build a web page.
- Dark61%. Frosted glass panels43%. Large rounded corners43%. Neon glow shadows37%
Least default
Scored on 19 web challenges. Each page is compared with the pages other labs shipped before it, matched for length. 50 is the middle of that crowd. Lower means fewer defaults.
- GPT-5.1-Codex
- Gemini 2.5 Pro Preview 06-05
- Muse Spark 1.1
- GPT-5.3-Codex
- GPT-5.6 Luna Pro
- Horizon Alpha
- Kimi K2.6
- Healer Alpha
- MiMo-V2-Flash
- GPT-5.2
- GPT-5.1 Codex Max
- GPT-5.6 Sol
- DeepSeek R1 0528
- GLM 4.5
- Qwen3 30B A3B Thinking 2507
- Horizon Beta
- Kimi K2
- GPT-5.6 Terra
- MiniMax M1
- Gemini 3 Flash Preview
- Muse Spark 1.3
- Muse Spark 1.3 Contributor
- Qwen3.5 27B
- Claude Opus 4.6
- Inkling
- Gemma 3n 2B
- Qwen3 Coder Flash
- Qwen3.5 397B A17B
- MiniMax M2.1
- GLM 4.6
- MiniMax M2
- GLM 4.5 Air
- MiniMax M2-her
- Seed 2.0 Lite
- Qwen3.5 35B A3B
- Claude Opus 4
- Nemotron 3.5 Lightning
- GPT-5.4
- MiniMax M2.5
- Gemini 3.5 Flash
- Qwen3.5 122B A10B
- Gemini 2.5 Flash Preview 09-2025
- GPT-5.4 Mini
- Qwen3.5 Flash
- Claude Sonnet 4
- Qwen3.5 9B
- GPT-5.1
- GPT-5 Nano
- Qwen3 Coder
- GPT-5
- Sherlock Dash Alpha
- Qwen3 Coder Plus
- Qwen3.5 Plus 2026-02-15
- Gemma 4 26B A4B
- GPT OSS 120B
- Qwen3 235B A22B Thinking 2507
- MiMo-V2.5
- Elephant Alpha
- Andromeda Alpha
- Sonar Pro Search
- Claude Opus 4.7
- Claude Sonnet 4.6
- Qwen3 Coder Next
- Claude Opus 5
- GPT-5 Mini
- Claude Opus 4.5
- Nemotron 3 Ultra
- MiniMax M2.7
- Qwen Plus 0728 (thinking)
- Sherlock Think Alpha
- Gemini 3.1 Pro Preview
- GPT-5.5
- Mercury
- Qwen3 Next 80B A3B Thinking
- Qwen3 30B A3B Instruct 2507
- Kimi Linear 48B A3B Instruct
- Grok 4.20 Beta
- OpenRouter Fusion · Quality (Jun 2026)
- Qwen3.6 Plus Preview (free)
- Gemini 3.7 Flash
- GPT-5.4 Nano
- Mistral Large 3 2512
- Grok 4.6
- Mistral Medium 3
- Gemini 3.8 Flash
- Kimi K3
- Kimi K2.7 Code
- Grok 4.1 Fast
- Mistral Small 4
- Ling 2.6 Flash
- LFM2.5-2.6B
- GPT-5.2 Chat
- Qwen3 Max Thinking
- Qwen3.6 35B A3B
- Gemma 4 31B
- Solar Pro 3
- Amazon Nova 2 Lite
- GPT-5.1 Chat
- DeepSeek V3.1
- Kimi K2 0905
- Claude Opus 4.8
- Gemini 3.6 Flash
- DeepSeek V4 Pro
- Gemma 3n 4B
- Claude Sonnet 5
- Ox Alpha
- Ling 2.6 1T
- Nova Premier 1.0
- Qwen3.7 Max
- Grok 4.3
- Mistral Small Creative
- North Mini Code
- Qwen3 Max
- Qwen3.6 Flash
- MiMo-V2.5-Pro
- NVIDIA Nemotron Nano 9B V2
- GPT-5.3 Chat
- GPT OSS 20B
- INTELLECT-3
- Qwen3 235B A22B
- GLM 4 32B
- Granite 4.2 8B
- Claude Fable 5.1
- Mercury 2
- Qwen3.5 Plus 2026-04-20
- Qwen3.6 Max Preview
- Gemini 2.5 Flash Lite Preview 09-2025
- Mistral Medium 3.1
- Claude Opus 4.1
- Grok Code Fast 1
- Gemini 2.5 Pro (I/O Edition)
- TNG R1T Chimera
- Claude Fable 5
- DeepSeek V3.2 Speciale
- Ring 2.6 1T
- Devstral 2 2512
- NVIDIA Nemotron 3 Super (free)
- Mistral Devstral Medium
- Qwen3.7 Plus
- Qwen3.6 27B
- Gemini 3.1 Flash Lite
- Dots3-Note Preview
- Claude Haiku 4.5
- DeepSeek V4 Pro 0813
- Kimi K2 Thinking
- Claude Sonnet 4.5
- Grok 4.5
- Qwen Plus 0728
- Seed 2.1 Turbo
- Mercury 2.5 Preview
- MiMo-V2-Pro
- Bert-Nebulon Alpha
- DeepSeek V4 Flash 0731
- Sonoma Sky Alpha
- Gemini 3.1 Flash Lite Preview
- Mistral Devstral Small 1.1
- Qwen3 Next 80B A3B Instruct
- MiMo-V2-Omni
- Qwen3 235B A22B 2507
- DeepSeek V4 Flash
- ERNIE 4.5 300B A47B
- Hy4 Preview
- Seed 2.0 Code
- Aurora Alpha
- DeepSeek V3.2 Exp
- Grok 4 Fast (free)
- MiniMax M3
- Grok 4
- Owl Alpha
- Cypher Alpha (free)
- Sonoma Dusk Alpha
- DeepSeek V3.2
- Qwen3 30B A3B


39 more models have fewer than six web pages and wait for a score.
The defaults move
Share of models doing each thing, by release date. Web habits are averaged across challenges so the prompt mix can't fake a trend.
Rising
- Something glowingSurprise animal33% → 86%
- Round line capsSVGs10% → 67%
- Uppercase tracked labelsWeb pages1% → 45%
- Frosted glass panelsWeb pages2% → 51%
- DarkWeb pages · theme21% → 63%
- FirefliesSurprise animal7% → 32%
- StarsSurprise animal7% → 71%
- ThorneThe professor's name4% → 13%
Fading
- LightWeb pages · theme79% → 38%
- The Dark Side of the MoonFavorite album39% → 10%
- The Shawshank RedemptionFavorite movie26% → 19%
- System sansWeb pages · typeface59% → 33%
- ChenThe professor's name24% → 4%
Before 2025 to 2026 H2, by model release date. Hover a line for each half-year.
Kyoto is not a personality
Split the web challenges in two and both halves agree on who is default (reliability 0.76). Do the same with the answers on the shelf and they agree on almost nothing (0.08). A model that picks Kyoto is no more likely to tell the scarecrow joke. Those defaults belong to the whole field, so they stay on the shelf and out of the score.
How it works
What gets measured
19 web challenges, from a Linear clone to a Pokémon battle screen. Each page is reduced to the choices it made: typeface, light or dark, accent colour, icon set, and 23 habits like frosted glass, gradient text, glow, emoji icons, uppercase labels and floating animations. A habit a page skips is not counted, so doing less makes a page neither more nor less default.
Who it is compared with
Every page another lab shipped for the same prompt before this model came out. A lab's own earlier models are not the crowd, they are the family. Labs with many variants count less: each lab weighs the square root of its model count, so a lab with sixteen variants counts as four.
How the score works
A page's typicality is its average overlap (Jaccard) with every earlier page. Its percentile is where that lands among the earlier pages closest to it in length, because longer pages carry more of everything. The Default score is the mean percentile across a model's pages, with a 90% bootstrap interval. A model needs 6 pages to get one. Scores freeze at release: a newer model never moves an older model's score.
Checks
Split-half reliability across web challenges: 0.76. SVGs (0.293) and the shelf answers (0.08) are too unstable per model to score, so they are reported, not ranked. Page length against percentile after matching: -0.106. Stealth builds and the model they turned out to be land 10.6 points apart on average; random pairs from different labs, 16.7.
What it is not
Not a quality score. A default page can be a good page, and the most original page in the set may not load. One sample per model per prompt, so this describes the field, not a model's own variety. The prompts have been public since 2025, and later models may have read earlier answers. That would make them more default, which is the thing being measured.
How it updates
Recomputed from the archive on every build. No judge, no API calls, no human in the loop. A new model is scored the day its web challenges land. The method is versioned; any change to it bumps the version on this page and in the dataset.
Cite it
Rival (2026). The Default Index, v1.0. https://www.rival.tips/default-index. Data through 2026-09-04.
Also on Rival: SubjectiveBench, the challenges, every model.
This page is dark, like 61% of the pages it measures.